Built to be examined.
MELRA: our open-source execution layer for AI agents.
See it run.
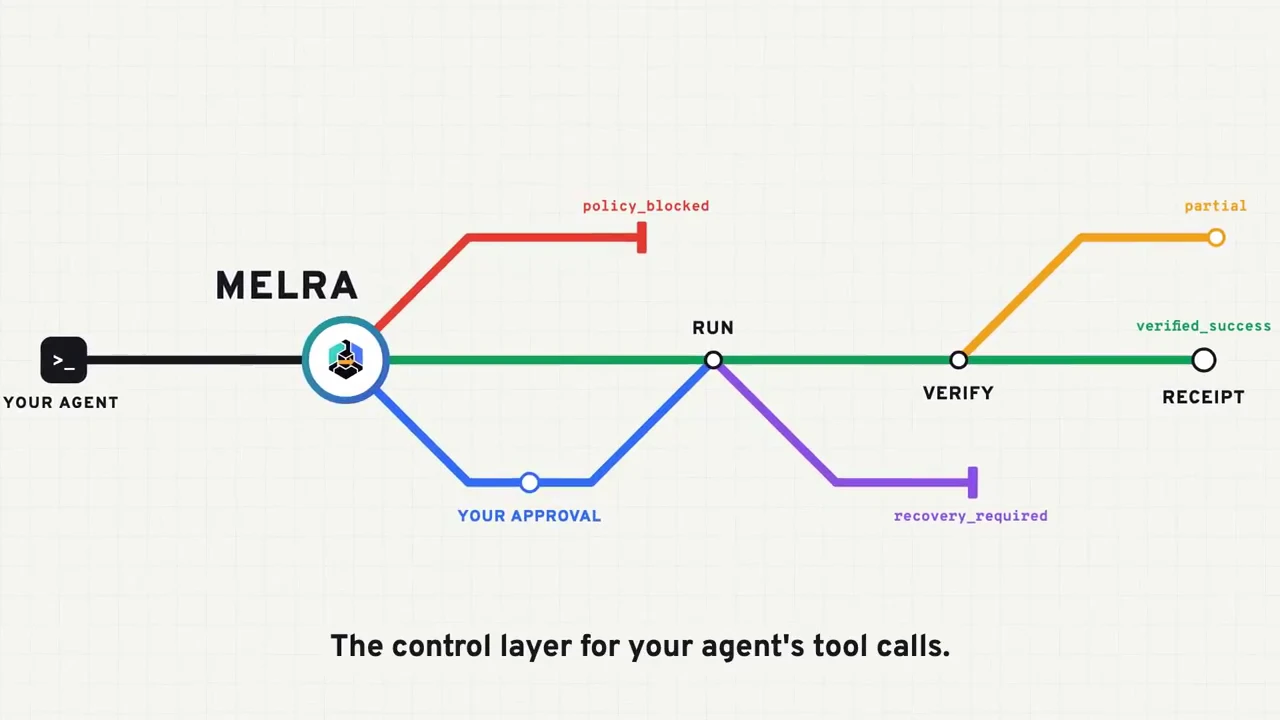
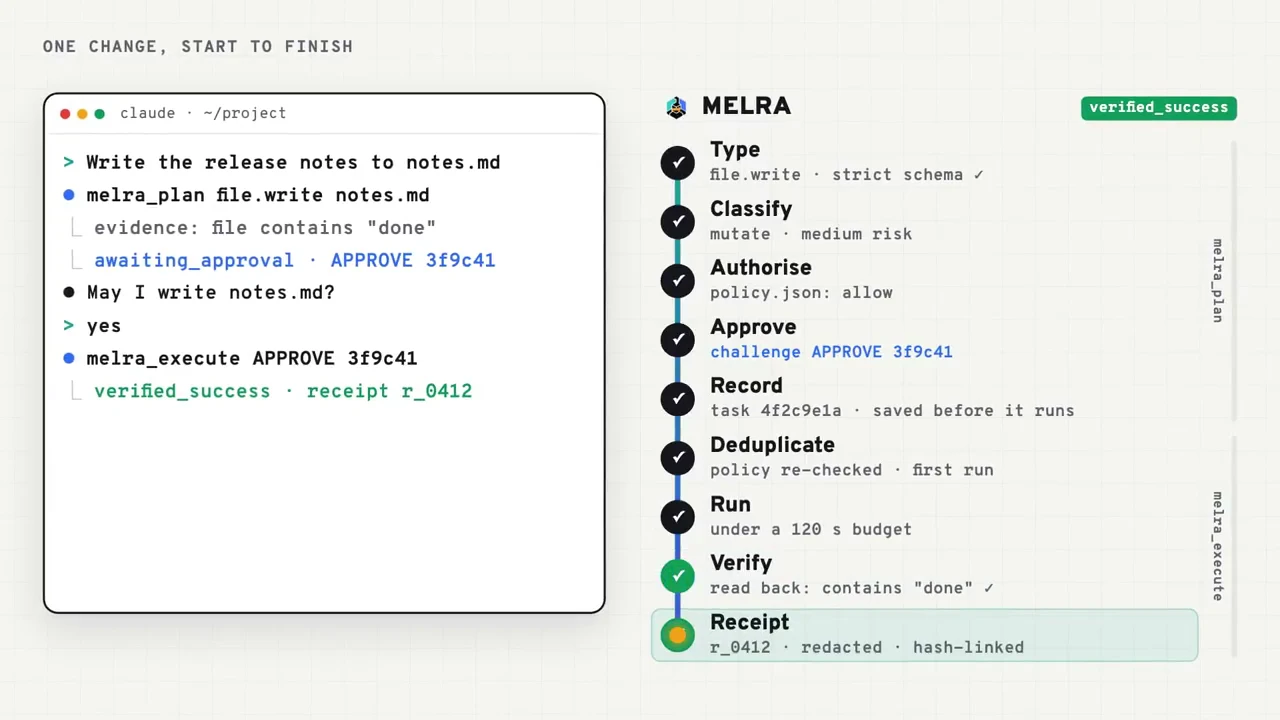
Watch on GitHubAn agent asks MELRA to act. Each action is checked against the policy, then allowed, refused before anything runs, or held for a person’s exact approval. What runs counts as done only if the evidence asked for holds, and every action ends in a hash-linked receipt.
Four questions,
every action.
Whichever model or agent asked.
Is it allowed?
Checked against your policy, twice. Risky changes wait for you.
Did it really work?
Only if the evidence you asked for holds.
What if it crashes?
Recorded first, run at most once, never blindly repeated.
What happened?
A hash-linked receipt for every action.
Every action
ends in a state.
Pick what happened. See how MELRA reports it.
verified_successDone. The receipt shows what ran and why it was allowed.
partialIt ran, but the evidence did not hold. Look before deciding.
policy_blockedRefused before anything ran.
awaiting_approvalWaiting for a person’s exact approval.
recovery_requiredIt may or may not have happened. Check the world first; never re-run blindly.
Try it in
one command.
Node.js 22+. Works with Claude Code, Cursor, Codex, Gemini CLI and any MCP client.
Read how it works.
At the commit this site’s numbers come from, ab59ffa.
Why it
is open.
You cannot trust a control layer you are not allowed to read.